
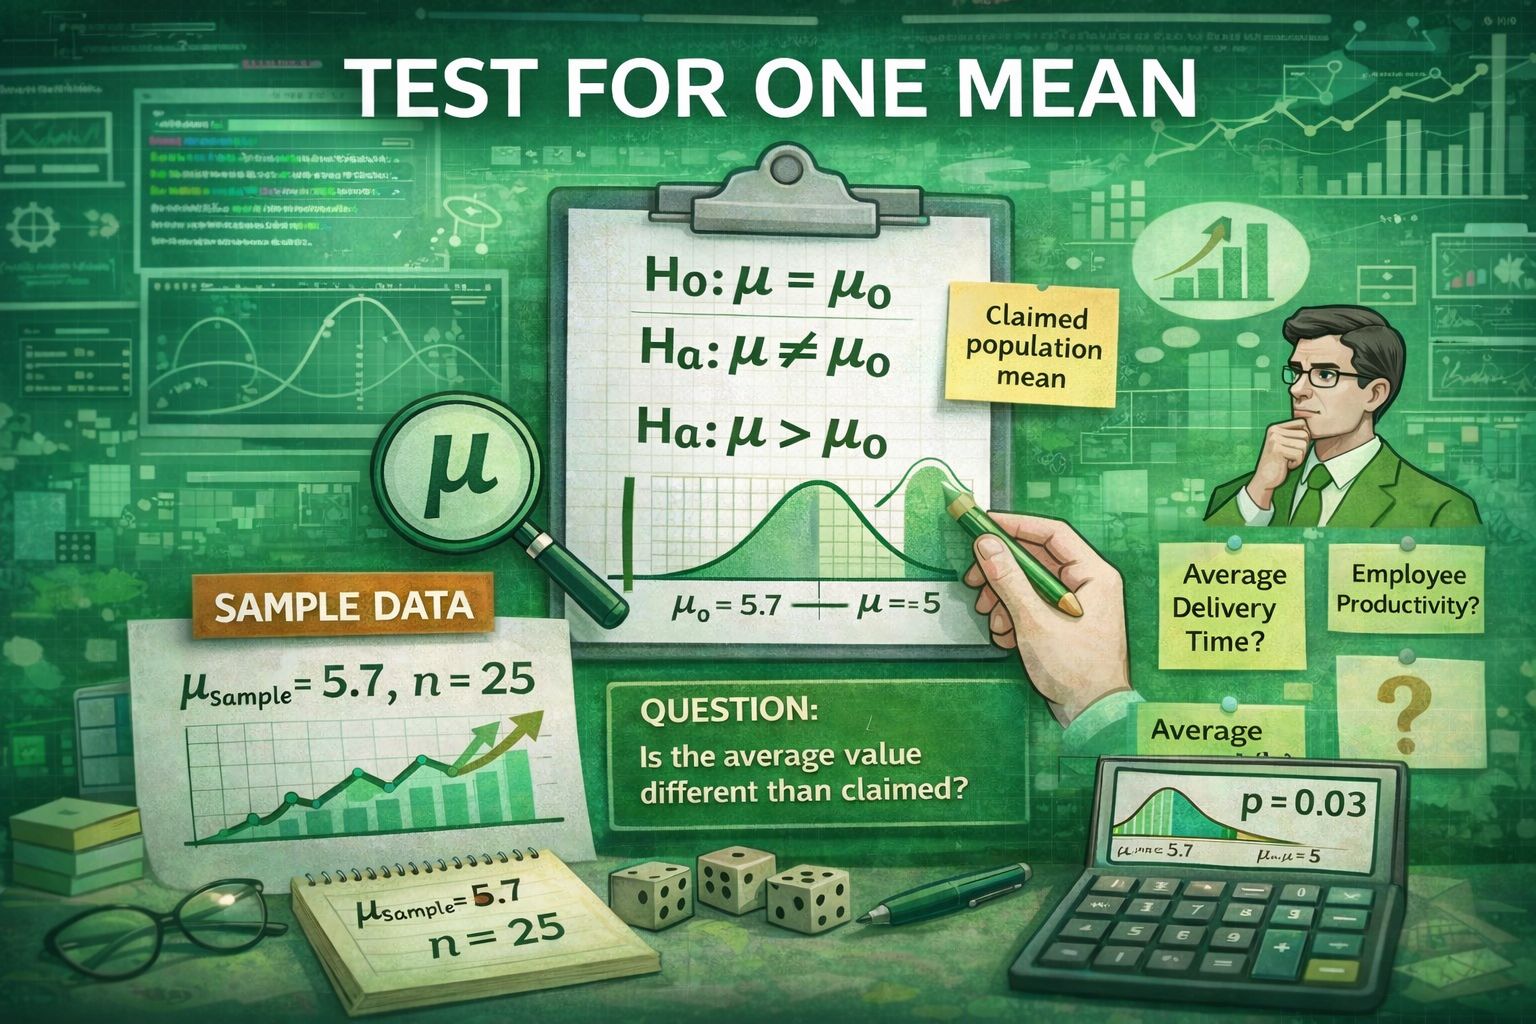
As you move deeper into business statistics, you begin shifting from describing data to making decisions based on it. Confidence intervals and hypothesis testing introduced this idea by showing how sample data can be used to say something about a larger population. The test for one mean builds directly on those ideas and gives you a clear, structured way to evaluate claims about an average.
What Does “Test for One Mean” Mean?
A test for one mean is a statistical procedure used to compare a sample mean to a specific value that represents a claim or benchmark about a population mean. In notation, that benchmark is usually written as 𝜇0.
In plain terms, you are asking a question like this: Is the average value we are observing different from what we expected or were promised? The answer is based on probability rather than certainty, which is why this test falls under inferential statistics.
When You Would Use a Test for One Mean
This test is useful whenever a single average matters to a business decision. For instance, you might want to check whether the average delivery time still meets a service-level agreement, whether the average cost per unit has increased, or whether employee productivity has changed after a new policy was introduced.
In all of these cases, the structure is the same. You collect a sample, compute its mean, and compare it to a known or claimed value. The goal is not to prove anything with absolute certainty, but to assess whether the observed difference is large enough to matter statistically.
Setting Up the Hypotheses
Every test for one mean starts with hypotheses. These translate a business question into statistical language.
The null hypothesis represents the status quo or the claim being tested:
𝐻0 : 𝜇 = 𝜇0
The alternative hypothesis represents what you suspect might be true instead. Depending on the situation, it can take one of three forms:
𝐻𝑎 : 𝜇 ≠ 𝜇0
𝐻𝑎 : 𝜇 > 𝜇0
𝐻𝑎 : 𝜇 < 𝜇0
If you are checking for any change at all, you use a two-sided alternative. If you are specifically looking for an increase or a decrease, you use a one-sided alternative. This directly connects to the one-tailed and two-tailed tests discussed earlier.
Choosing the Right Test: Z-Test or T-Test
There are two common versions of the test for one mean. Which one you use depends on what you know about variability and how much data you have.
A one-sample Z-test for the mean is used when the population standard deviation is known or when the sample size is large enough for the Central Limit Theorem to apply. In practice, this is less common in business settings.
A one-sample T-test for the mean is used when the population standard deviation is unknown, which is the usual case. The T-test adjusts for extra uncertainty when working with smaller samples.
From a manager’s perspective, the key point is that both tests follow the same logic and lead to the same kind of decision. The difference lies in how uncertainty is handled mathematically.
The Role of the Test Statistic
Once hypotheses are set, the next step is computing a test statistic. The test statistic measures how far the sample mean is from the hypothesized mean, relative to the expected variation.
In general form, the statistic looks like:
Test Statistic = Sample Mean -𝜇0Standard Error
This value tells you how unusual your sample result would be if the null hypothesis were true. A value close to zero means the sample is consistent with the null. A value far from zero suggests a meaningful difference.
Because this statistic follows a known sampling distribution, you can evaluate it using probability.
Significance Level, Rejection Regions, and p-Values
Before looking at results, you choose a significance level, written as 𝛼. Common choices are 0.10, 0.05, or 0.01. This level defines how much risk you are willing to accept when rejecting the null hypothesis.
The significance level determines rejection regions in the sampling distribution. If your test statistic falls into one of those regions, you reject the null hypothesis. Otherwise, you fail to reject it.
An equivalent way to make this decision is by using the p-value. The p-value tells you how likely it is to observe a result as extreme as yours if the null hypothesis were true. When the p-value is less than 𝛼, the null hypothesis is rejected.
A Step-by-Step Business Example
Let’s look at a practical example. Suppose a company claims that its average customer support response time is 30 minutes. You want to check whether this claim still holds.
You take a random sample of recent tickets and find:
- Sample mean response time = 33 minutes
- Sample standard deviation = 8 minutes
- Sample size = 50
You set up the hypotheses:
- 𝐻0 : 𝜇 = 30
- 𝐻𝑎 : 𝜇 ≠ 30
You choose a significance level of 𝛼 = 0.05. Since the population standard deviation is unknown, you use a one-sample T-test.
After computing the test statistic, you obtain a p-value of 0.02. Because this value is smaller than 0.05, you reject the null hypothesis.
From a business standpoint, this means there is sufficient statistical evidence to conclude that the average response time is no longer 30 minutes. That insight can trigger operational reviews, staffing changes, or revised performance targets.
Interpreting Results in Business Terms
Rejecting the null hypothesis does not mean the claim was “proven wrong” in an absolute sense. It means the observed data is unlikely under that claim, given the chosen level of risk.
Failing to reject the null hypothesis does not prove it is true. It simply means there is not enough evidence to say it is different from the benchmark.
This distinction matters in business. After all, decisions are made under uncertainty, and hypothesis testing helps you manage that uncertainty in a disciplined way.
Common Pitfalls to Watch For
One common mistake is focusing only on statistical significance and ignoring practical impact. A small difference can be statistically significant with a large sample but irrelevant in real operations.
Another issue is violating assumptions, such as independence or appropriate sample selection. These can undermine conclusions even if your calculations are correct.
Finally, it is important not to treat hypothesis testing as a one-time exercise. Its results should be combined with context, judgment, and other forms of analysis.
How the Test for One Mean Fits Into the Bigger Picture
The test for one mean is one of the most basic inferential tools, but it sets the foundation for many others. Confidence intervals, two-sample tests, and regression analysis all build on the same ideas of sampling distributions and probabilistic decisions. Mastering this test enables you to gain a clearer understanding of how data supports or challenges business claims.
Closing Thoughts
The test for one mean gives you a practical way to evaluate averages that matter to your organization. It helps turn raw sample data into structured evidence and allows you to make informed decisions while acknowledging uncertainty. Used thoughtfully, it becomes a reliable tool for navigating business questions in a data-driven way. In the next session, we’ll be talking about the test for equality of means or known standard deviation.

